Serverless inference, built for async AI.
Send your agents and batch jobs to one serverless endpoint,
and we run them on the cheapest capacity that fits.
No GPUs to manage, no rate limits, pay per token for your exact workload shape.
What you get
Up to 10x lower cost per token, with the most intelligence per dollar

Serverless, at any scale
No GPUs to provision, no rate limits, no idle capacity to pay for.
Most intelligence per dollar
The highest throughput per GPU on open models. Lower cost than serverless alternatives at scale.
Enterprise-ready
Uptime SLAs, SLOs from seconds to hours, and hands-on support from our team.
Run your workload, see the performance, then scale.
Spin it upSpin up a serverless endpoint on the open models you already run. OpenAI-compatible, no infrastructure to manage.

Run your workloadSend single requests, agent loops, or full batches - no rate limits, nothing to tune. We schedule around your deadline.
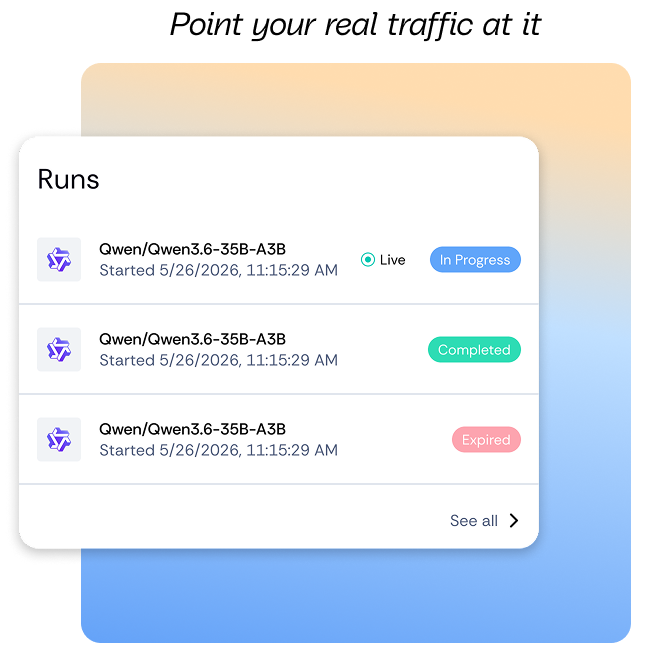
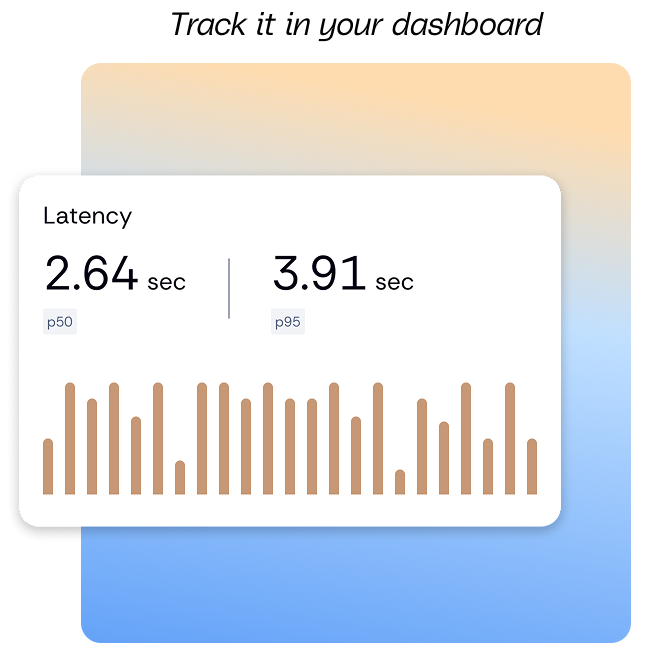
Watch it liveTrack throughput, latency, and cost on your own workload in real time. No report to wait for - you just see it working.
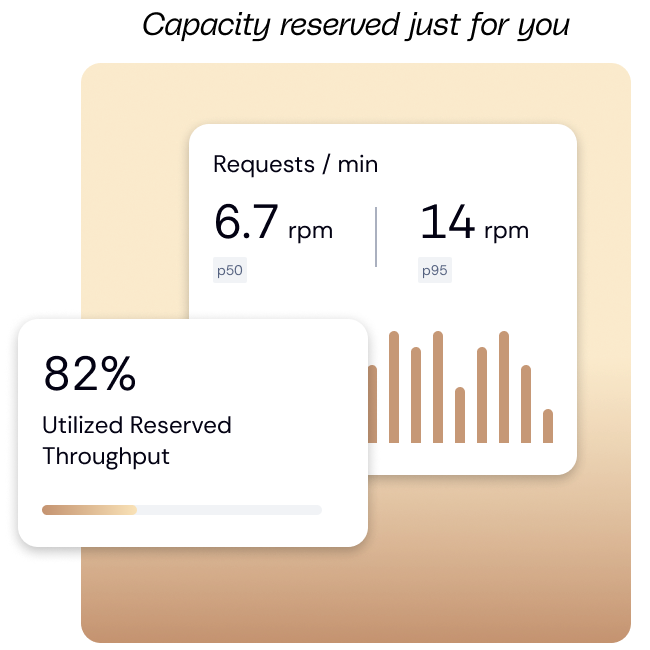
Scale it upGo from one batch to billions of tokens a day on the same endpoint. Need it locked in? Add single-tenant, reserved capacity.
Powered by the
Impala Herd engine
Serverless inference runs on Impala Herd - our inference engine that reshapes itself around your traffic: kernels, batching, decoding. Same hardware,
more tokens, lower cost per token.